Dictation has become one of the fastest-growing ways to write, and the best products are now very good. Almost all of them work the same way: your voice is recorded, sent to a server, transcribed by a model you never see, and returned as text.
So a message to your doctor, or a note about your company’s finances, leaves your device every time you speak. We don’t think accuracy should cost that.
Fluid Speech Mini is an open-weights English speech model for on-device dictation. It is a 253 MB Core ML package that scores level with the most accurate open Parakeet model at one fifth of the download, and it was trained for real-world use, including when someone else is talking nearby.
Parakeet accuracy in 253 MB
On the eight public English test sets of the Open ASR Leaderboard, Fluid Speech Mini gets 4.54% of words wrong. Moondream’s Parakeet Ultra gets 4.56%. The two are effectively level. Ultra is a 1.26 GB download; Fluid Speech Mini is 253 MB.
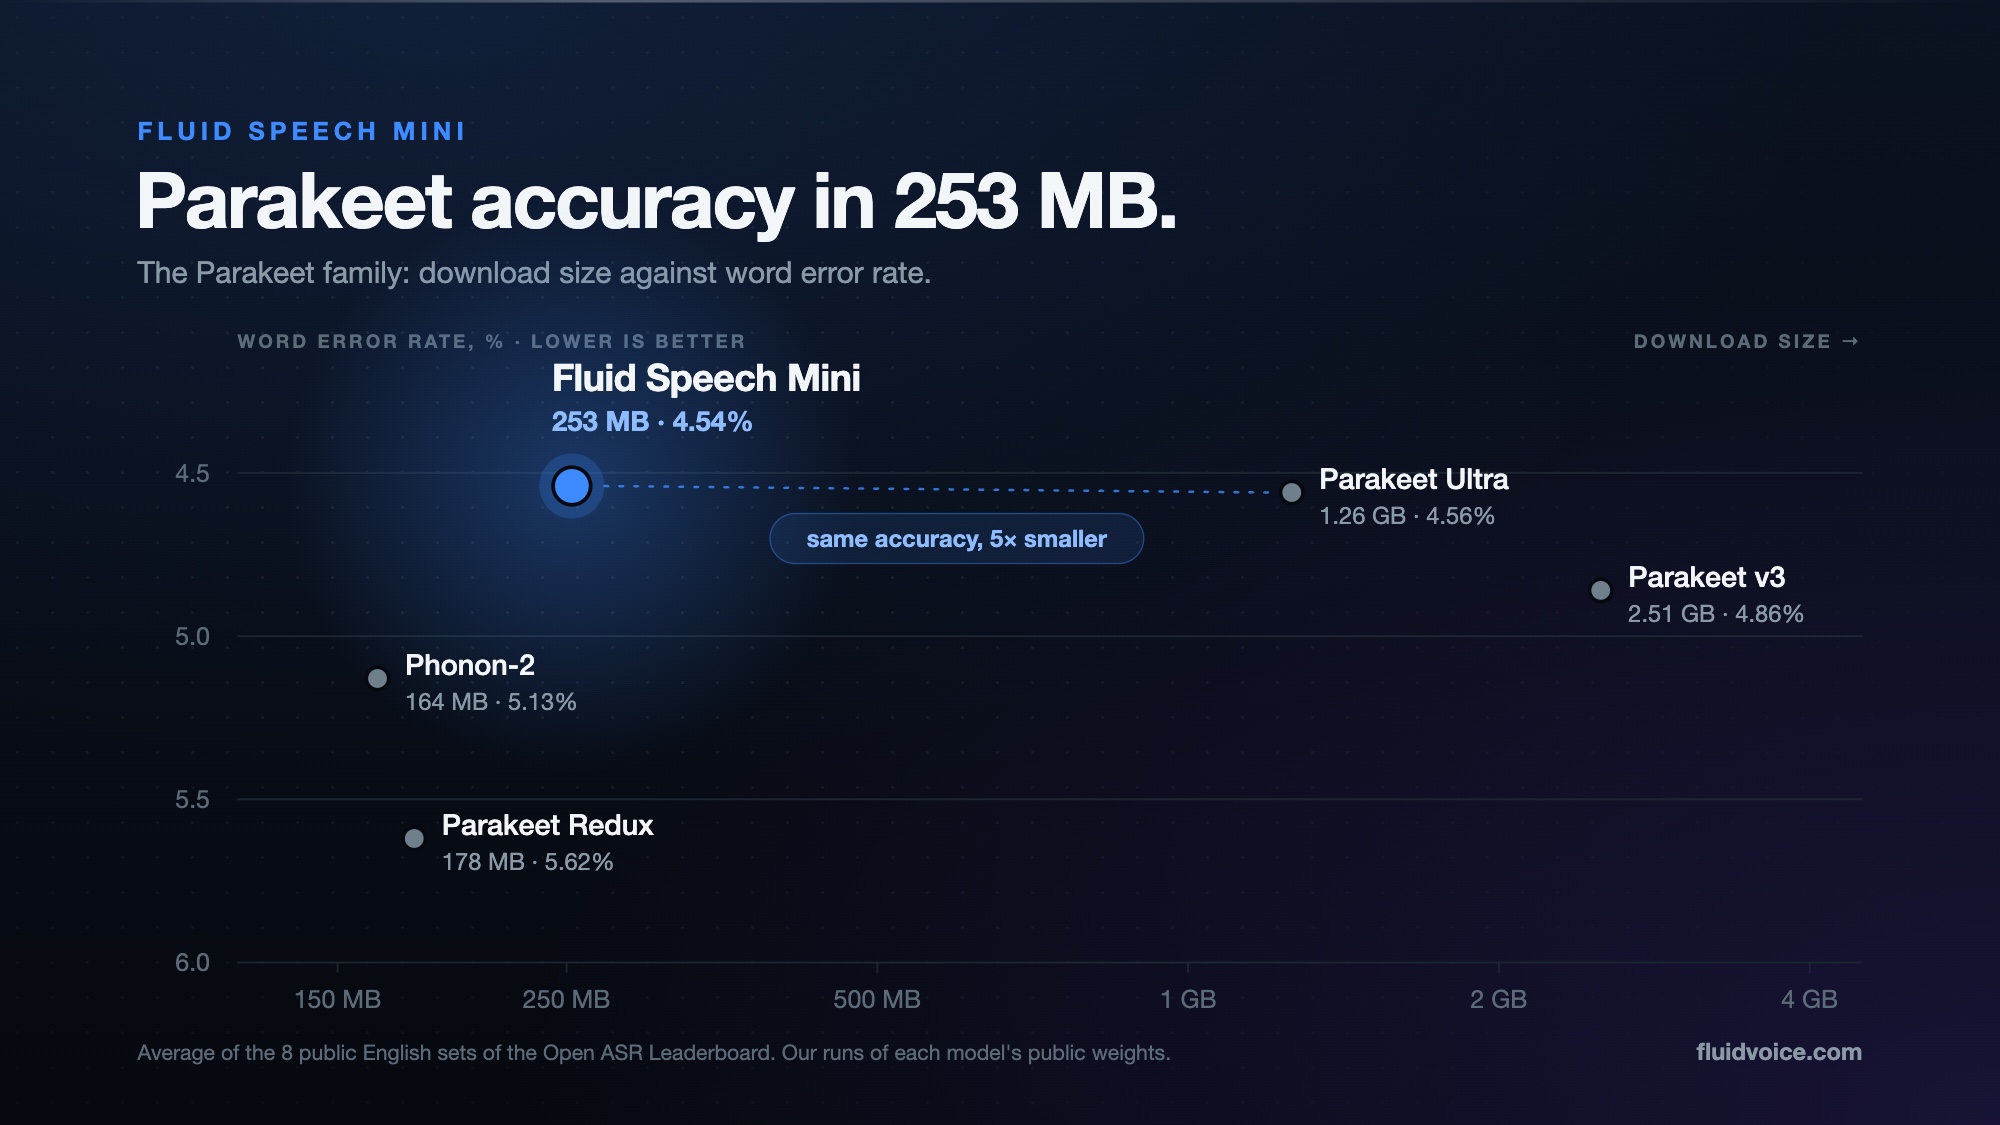
Phonon-2 (164 MB) and Parakeet Redux (178 MB) are smaller downloads and faster models, and both are impressive engineering. They give up accuracy to get there: Phonon-2 gets 5.13% of words wrong and Redux 5.62%. On clean speech that is 13% and 24% more errors than Fluid Speech Mini, and the gap grows once a second voice is in the room.
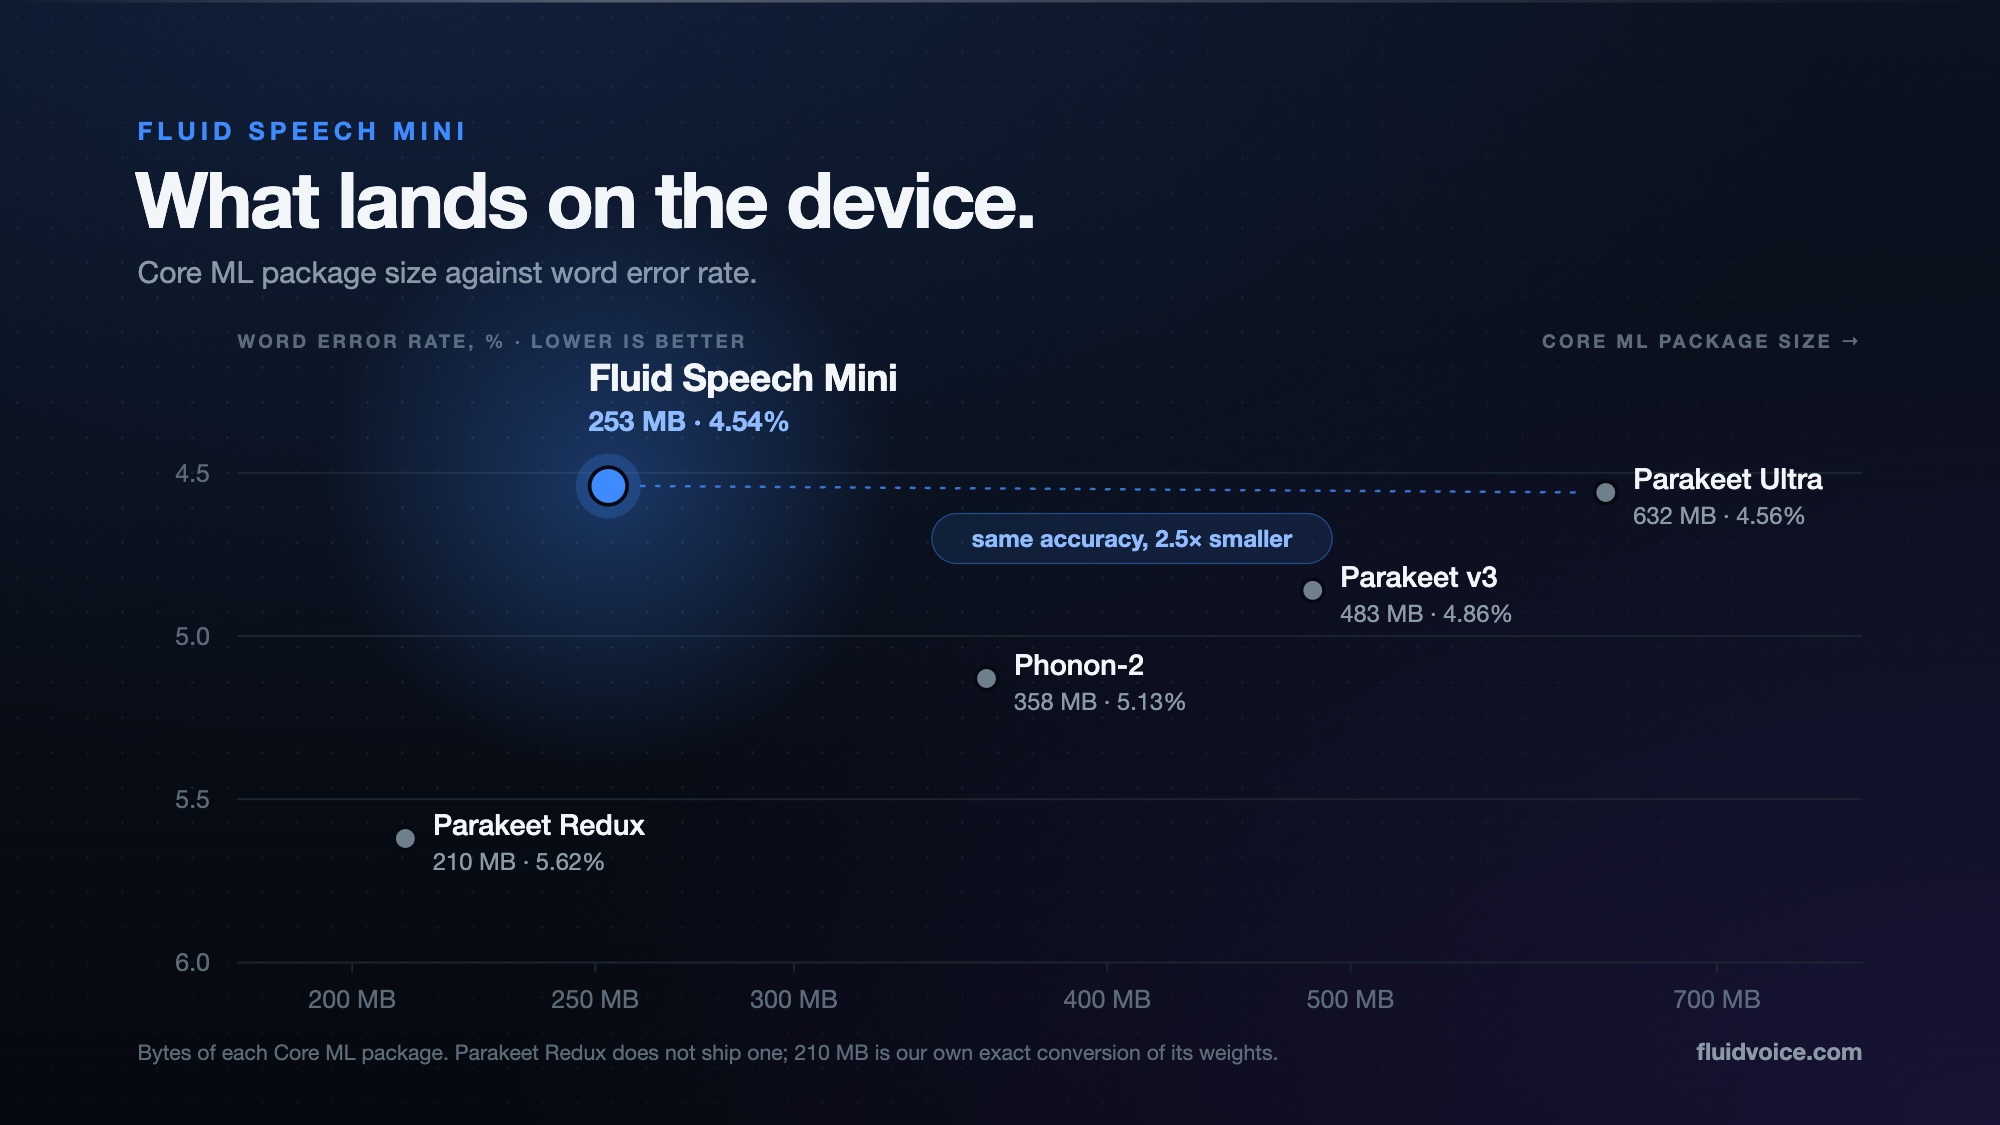
Download size is also not what ends up on the device. Parakeet Ultra’s 1.26 GB file stores its weights at 32 bits; in the 16-bit Core ML format Apple devices run, it is a 632 MB package. Phonon-2 goes the other way: its 164 MB download becomes a 358 MB Core ML package, and its own MLX runtime used about 1.3 GB of memory in our tests. Fluid Speech Mini was trained in the format it ships in, so the number holds: 253 MB to download, 253 MB as a Core ML package, and about 277 MB of memory while running.
| Model | Download | Average | AMI | Earnings-22 | GigaSpeech | LS clean | LS other | SPGISpeech | Monsoon | VoxPopuli |
|---|---|---|---|---|---|---|---|---|---|---|
| Fluid Speech Mini | 253 MB | 4.54 | 8.34 | 6.29 | 7.67 | 1.45 | 3.25 | 3.56 | 3.96 | 1.76 |
| Fluid Speech Pico (coming soon) | 159 MB | 4.64 | 8.60 | 5.93 | 7.82 | 1.63 | 3.64 | 3.51 | 4.14 | 1.81 |
| Parakeet Ultra | 1.26 GB | 4.56 | 8.39 | 5.68 | 7.64 | 1.41 | 2.99 | 3.35 | 3.84 | 3.16 |
| Parakeet v3 | 2.51 GB | 4.86 | 9.41 | 5.88 | 7.99 | 1.52 | 3.14 | 3.63 | 4.15 | 3.18 |
| Phonon-2 | 164 MB | 5.13 | 9.32 | 6.72 | 8.34 | 1.73 | 3.92 | 3.68 | 4.88 | 2.45 |
| Parakeet Redux | 178 MB | 5.62 | 9.07 | 7.85 | 8.62 | 1.96 | 4.35 | 3.91 | 5.37 | 3.86 |
When someone else is talking
Public benchmarks are mostly clean recordings of one person. Dictation rarely is. People dictate with the television on, beside a colleague’s call, in the car with children in the back seat. A second voice is the hardest case, because the model has to decide whose words to write down, and most write down both.
We used the English background-speech condition of Google SVQ. Every model ran on the same clips with the same scoring.
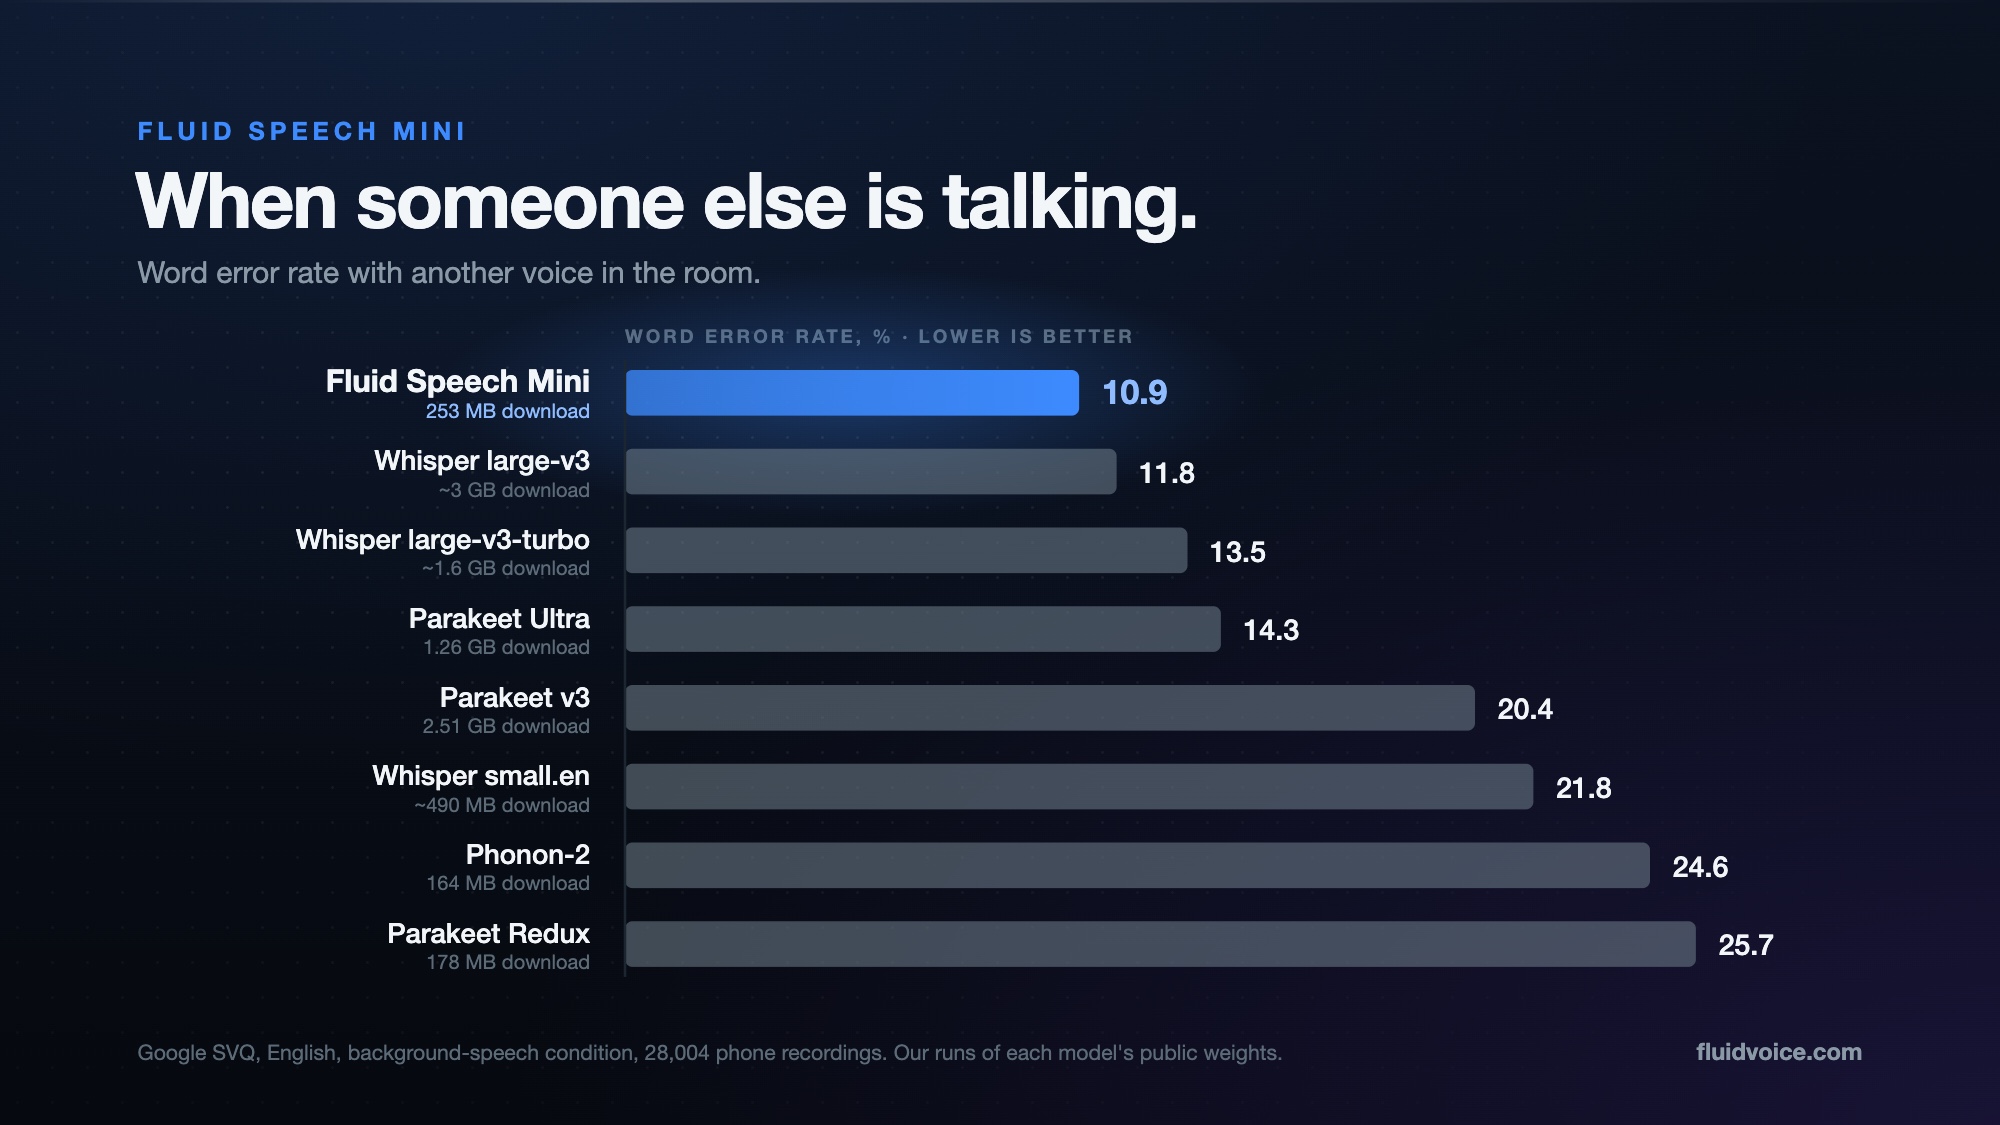
Fluid Speech Mini gets 10.9% of words wrong here. Parakeet v3, one of the two models it was built from, gets 20.4%, nearly twice as many.
This is the result you notice in use. Nobody feels a 0.2-point change on a leaderboard. Everybody feels a model that types a colleague’s conversation into their email.
How we built it
Small models usually lose accuracy because they are shrunk after training. We made the size limit part of training instead.
We started from NVIDIA Parakeet v3 and Moondream Parakeet Ultra and first trained a full-size teacher model for noisy rooms. That teacher scores 4.38% on the same eight test sets, better than either model it came from.
Fluid Speech Mini was distilled from that teacher. For each training clip, the teacher heard the clean recording while the student heard the same clip with noise, reverberation or a second speaker mixed in, and had to arrive at the same transcript. The teacher shows the student what was said; the student learns to ignore the rest.
The student was also small from the first step. Its weights are stored at about 3 bits each, where a conventional model uses 16, and it trained at that precision throughout, so there was never a full-size version to round down. The whole recipe trains on a single RTX 5090.
Open weights, on your device
Your voice is yours. With Fluid Speech Mini it stays on your device, full stop. There is no server to send audio to, no account to attach it to, and no network to depend on. It works on a plane, and in a hospital corridor with no signal.
We are releasing the weights because we think this is where speech recognition is going. Cloud models will keep improving, and we expect to compete with them on accuracy for a long time. But models keep getting smaller while phones keep getting more capable, and a model that runs on the device wins on privacy, latency and cost. Open weights let developers build on it, researchers check it, and users trust it for reasons other than a promise.
Fluid Speech Mini is English only for now. A smaller model for older devices and a multilingual version are next.
Try it in FluidVoice
Fluid Speech Mini is the speech model inside FluidVoice, our dictation app for Mac and iPhone. Pick it under Voice Engine, talk, and the text appears in whatever app you’re using. Our users compare it with the cloud dictation apps they came from, Wispr Flow, Superwhisper and Willow among them, and that is the comparison we want to be judged on.
Apple M5 Max · median of five runs · one synthetic-speech recording.
What you feel when dictating is the wait after you press stop. FluidVoice transcribes in chunks while you are still talking and keeps the results, so little is left to do at the end. In a simulated one-minute dictation on the same Mac, transcription finished about 0.04 seconds after the audio stopped.
How we measured it
Both tests ran with the model already loaded. The first is a complete one-minute file transcribed in one go. The second has chunk processing on and counts transcription only; it leaves out text cleanup and the time for the words to appear in your app.
On iPhone, FluidVoice is in TestFlight. Message us on X at @FluidVoiceApp and we will get you in.
Try FluidVoice for MacMethodology & limitations
Every number on this page is our own measurement, not an entry on the public leaderboard. We ran each model’s public weights ourselves. Accuracy is the average word error rate across the eight public English test sets of the Open ASR Leaderboard, using its evaluation code and text normalisation.
The background-speech test is the English background-speech condition of Google SVQ, scored the same way for every model. The advantage is specific to other voices: with traffic noise, the larger Parakeet and Whisper models did better, and some multi-gigabyte models also score better on background speech.
The model is trained and measured for English only. It shares a vocabulary with Parakeet v3, so other languages may come out, but we have not tested them. iPhone measurements for these weights are still to come.