 FluidVoice
A small, open speech-to-text model we built for dictation. It’s the most accurate open model under 1B parameters, and it’s live in FluidVoice today.
- #1open model at 1B parameters and under on the Open ASR Leaderboard. #2 of all open models at launch.
- 6.06%average word error rate. Lower is better.
- 0.6Bparameters, ahead of models up to 50× its size.
- 3,690×real time on one GPU: about an hour of audio in a second.
Why we built it
Fluid Speech Pro is that model. It has 0.6 billion parameters, works in 25 languages, and its weights are open under CC BY 4.0.
To see how it stacks up, we submitted it to Hugging Face’s Open ASR Leaderboard. It was our first time there. It came in #2 among open models at launch, and #10 of 66 once paid models were included. The ranking was a side effect, though. Better dictation was the goal.
How accurate it is
The leaderboard scores word error rate: the share of words a model gets wrong compared with a human transcript. Lower is better. Fluid Speech Pro averages 6.06% across the leaderboard’s seven public test sets and two private ones.
Word error rate on each test set
SPGISpeech is scored in clean mode.
- VoxPopuli1.70%
- SPGISpeechclean mode2.31%
- Voice Arena Monsoon3.71%
- Earnings-225.42%
- GigaSpeech7.51%
- AMI7.55%
- URGENT 20249.83%
Private sets: the board’s own, unpublished audio
- Scripted3.67%
- Conversational12.80%
Average of all nine6.06%
How it does for its size
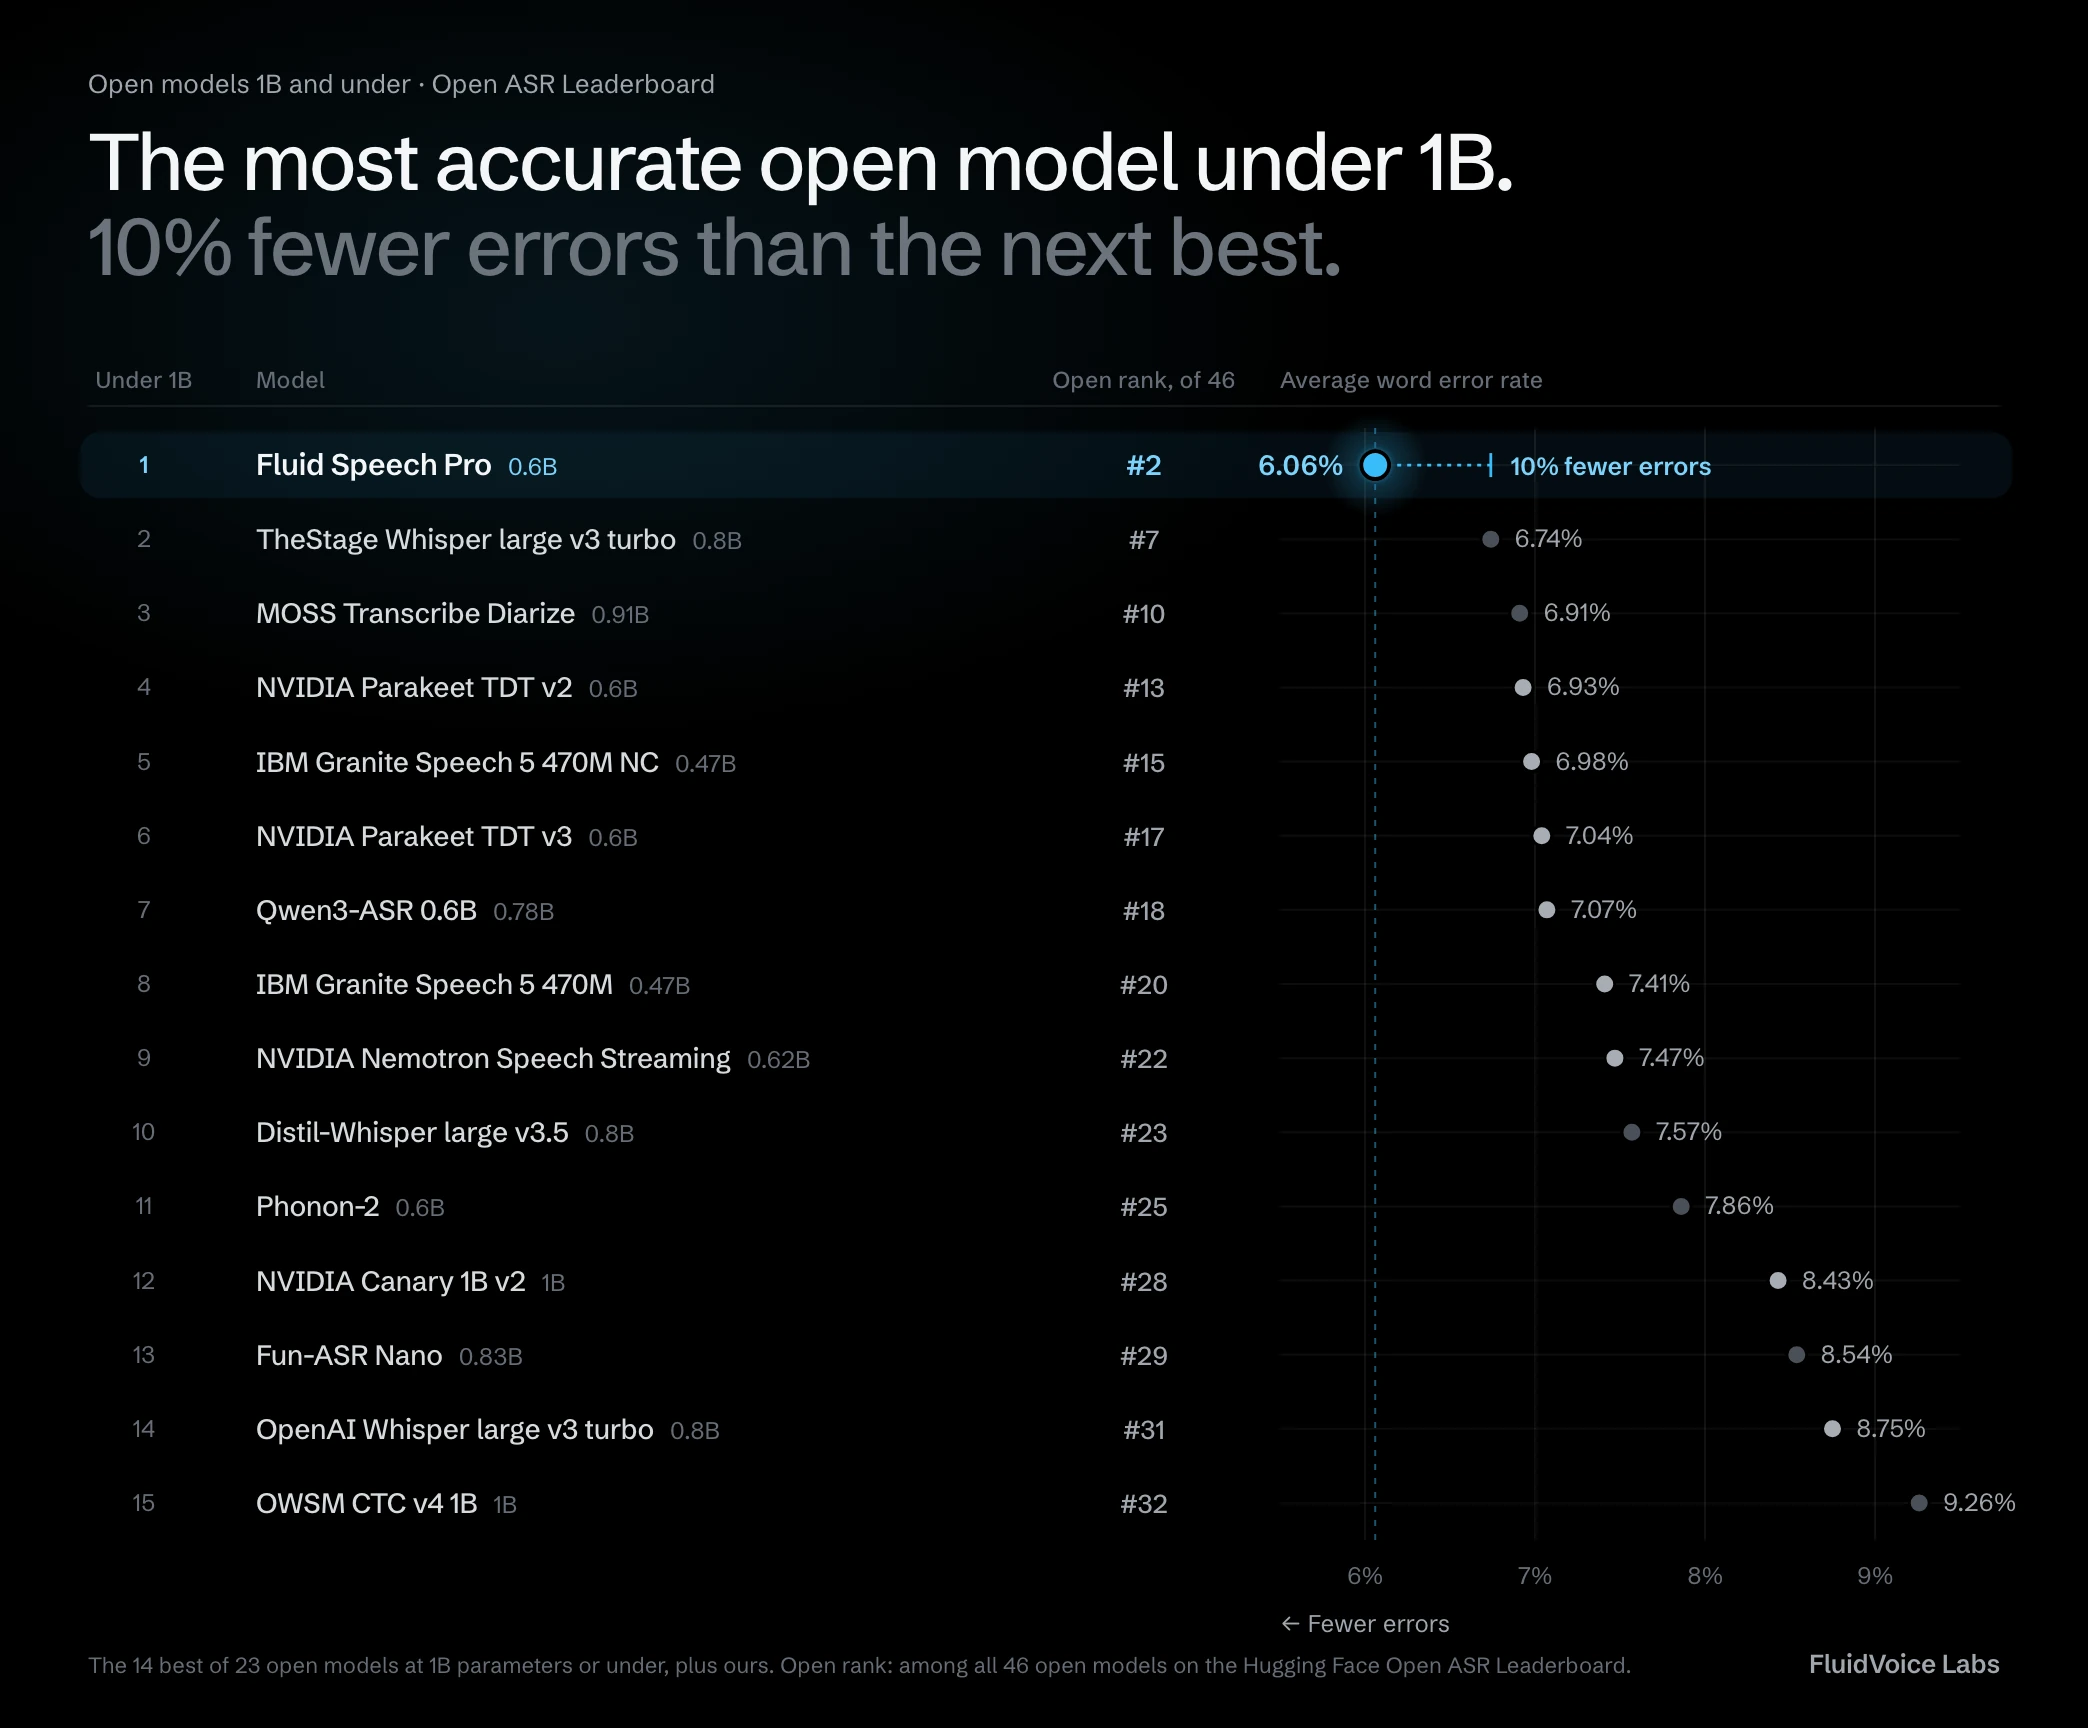
Fluid Speech Pro is small. At 0.6B parameters, it’s ahead of models up to 50 times its size. Among open models at 1B parameters and under, it’s the most accurate one, with 10% fewer errors than the next best.
It’s quick, too. On one GPU it runs at 3,690 times real time, which is about an hour of audio in a second.
How it handles noise
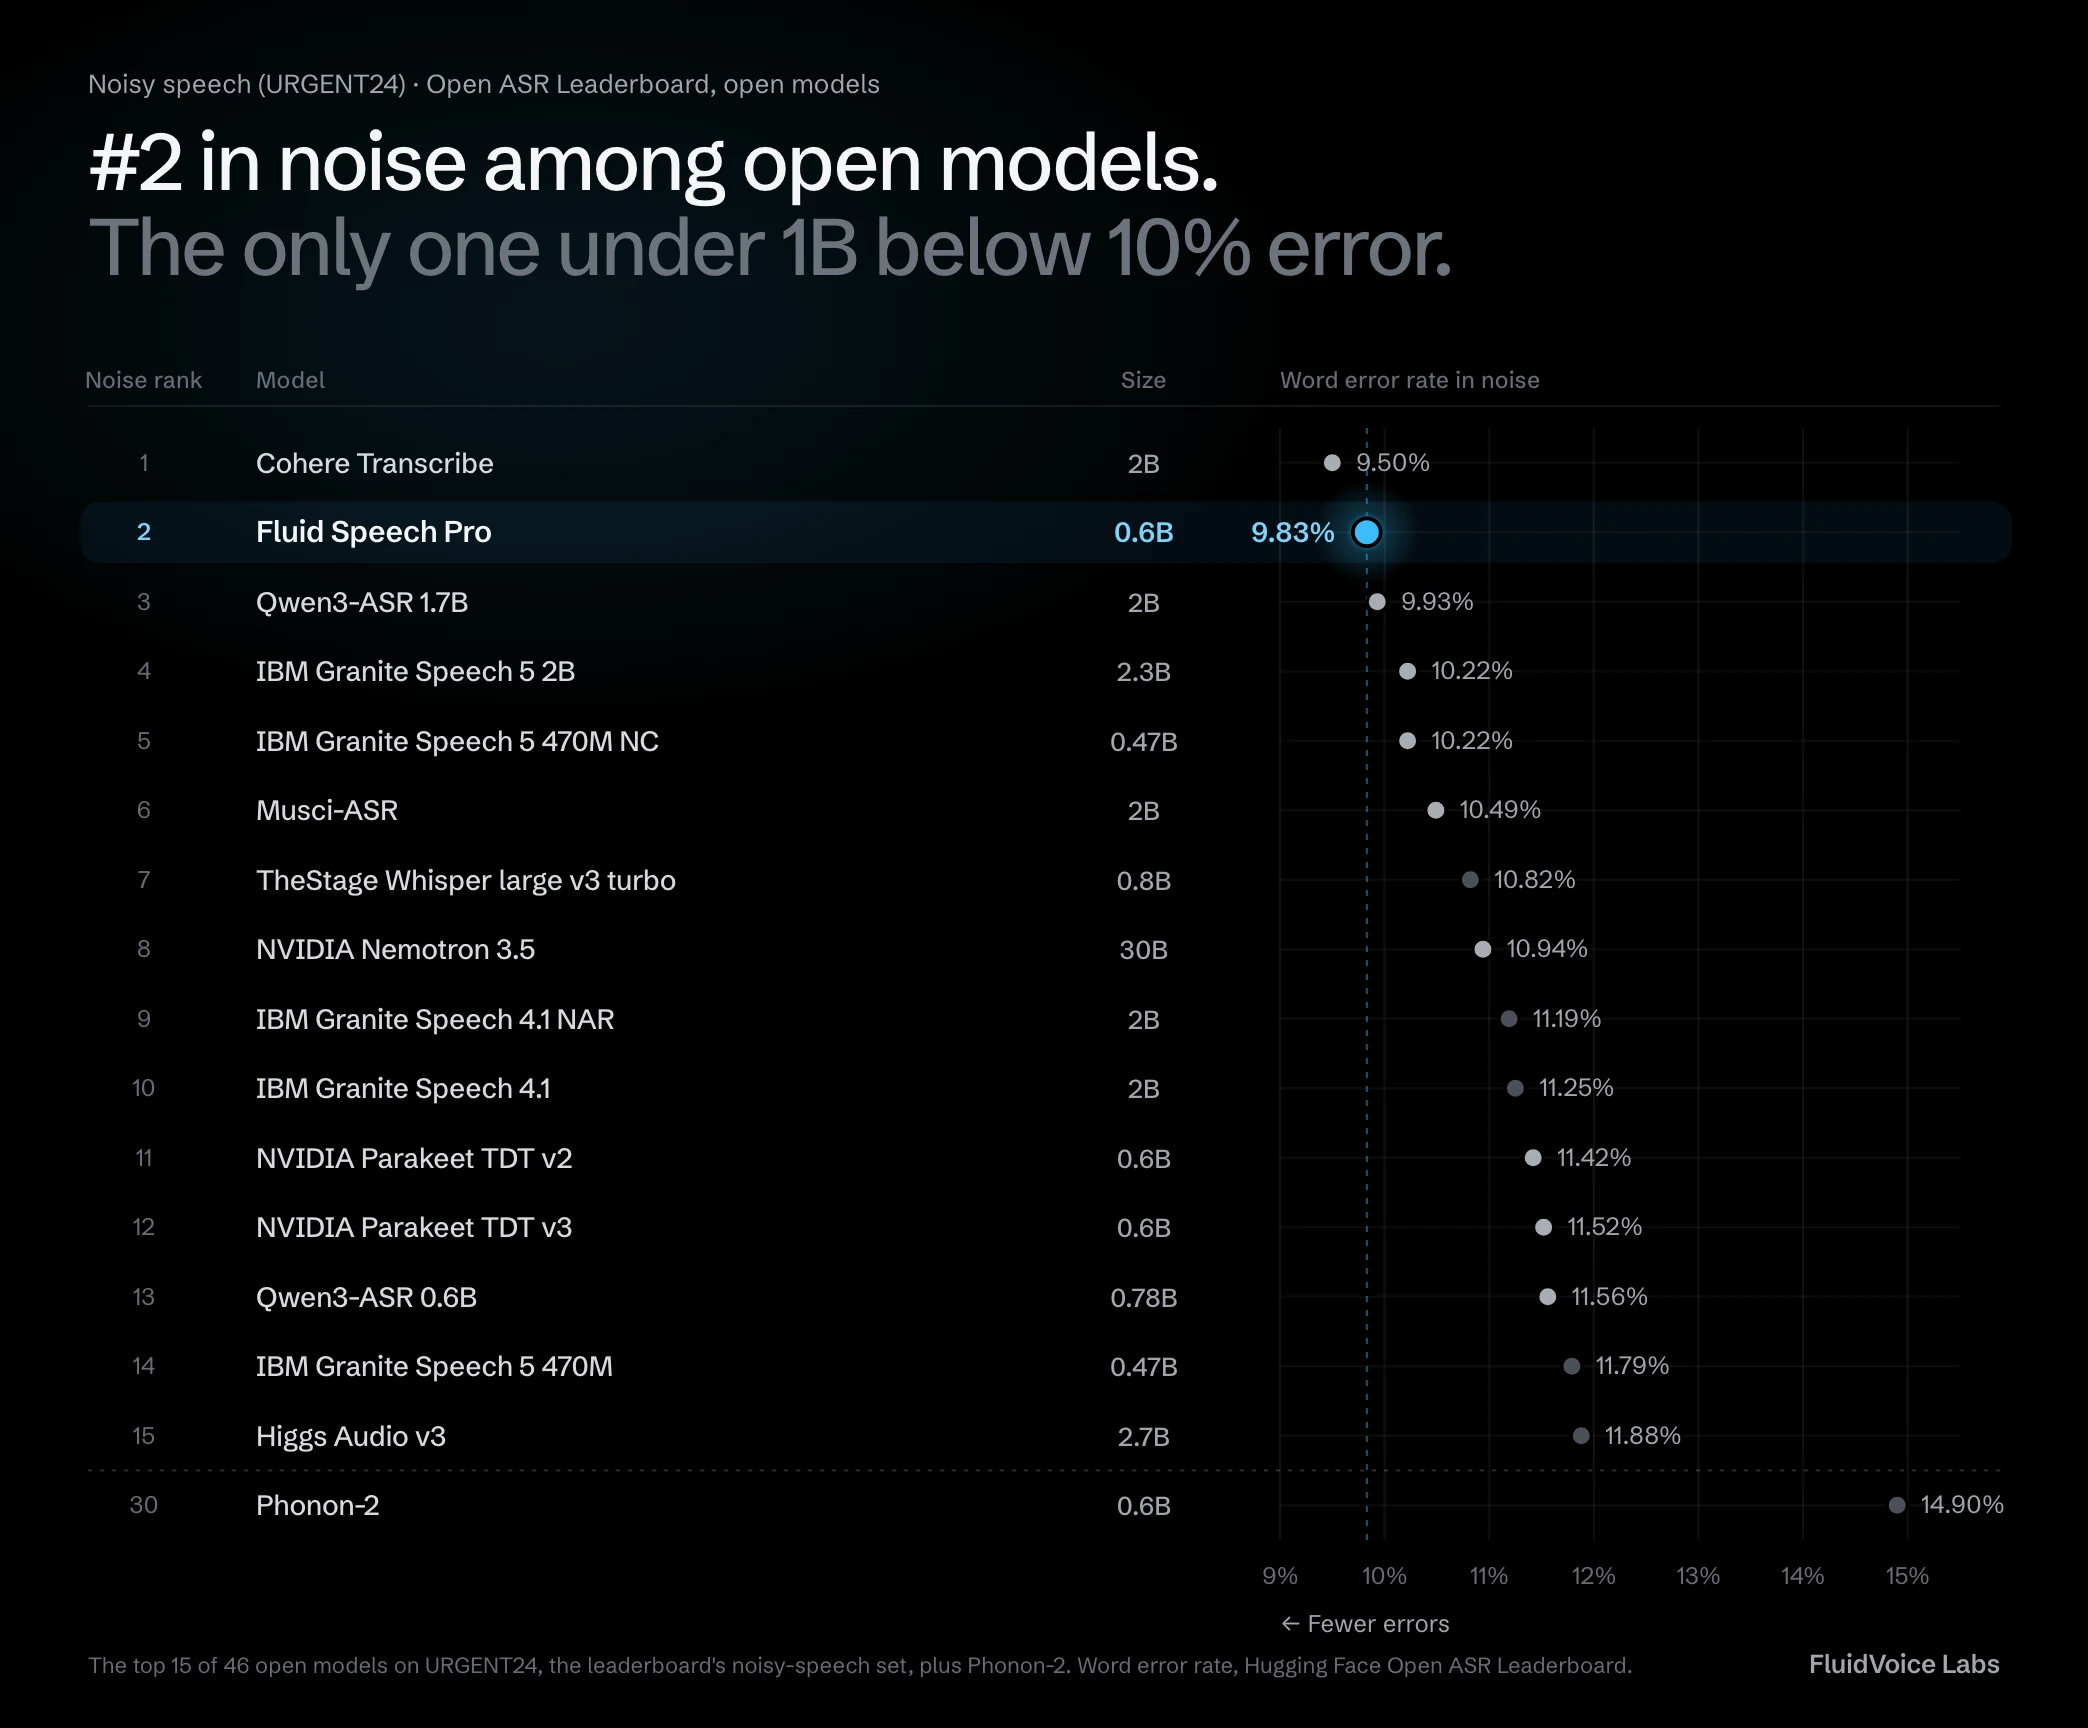
Dictation rarely happens somewhere quiet, so we care a lot about noise. URGENT 2024 is the leaderboard’s noisy-speech set. Fluid Speech Pro scores 9.83% word error rate there. At launch that was #2 among open models, and it’s the only open model under 1B that gets below 10%.
25 languages
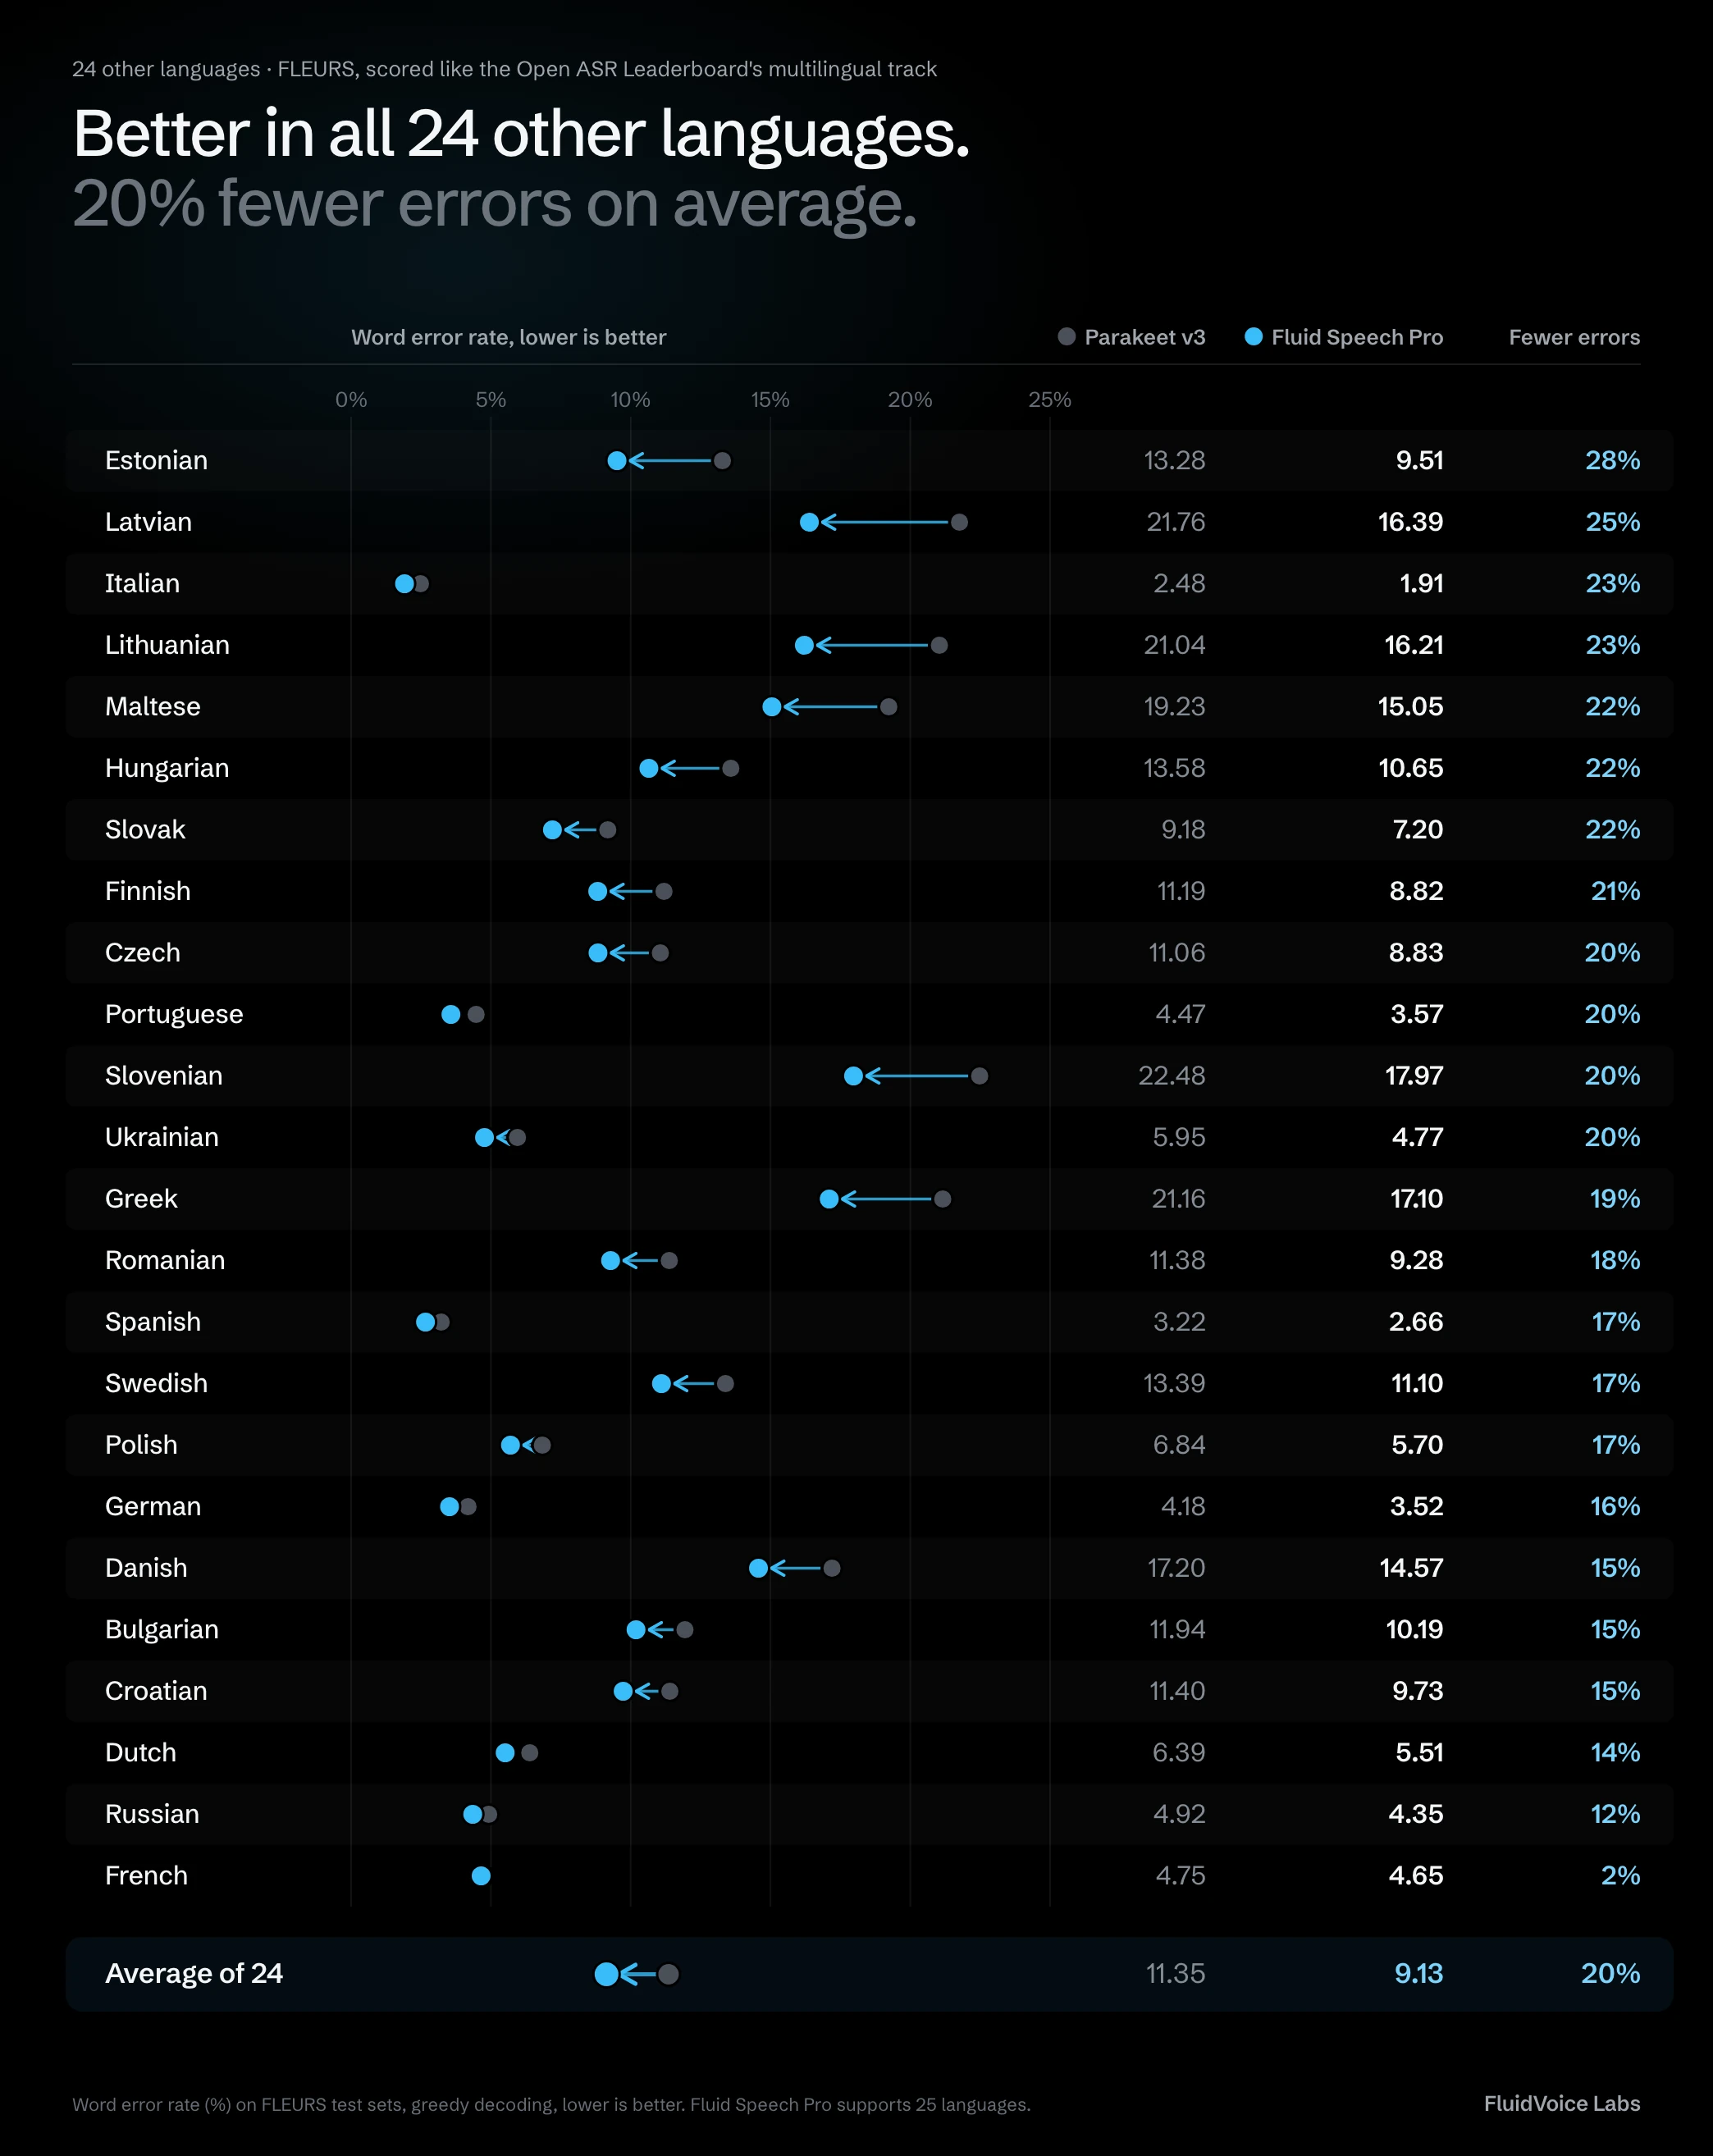
Fluid Speech Pro works in 25 languages and detects the language on its own, so there’s nothing to set. Compared with its base model, it makes fewer errors in all 24 languages beyond English, 20% fewer on average.
- English
- Bulgarian
- Croatian
- Czech
- Danish
- Dutch
- Estonian
- Finnish
- French
- German
- Greek
- Hungarian
- Italian
- Latvian
- Lithuanian
- Maltese
- Polish
- Portuguese
- Romanian
- Russian
- Slovak
- Slovenian
- Spanish
- Swedish
- Ukrainian
Clean mode
People don’t talk the way they write. We say “um” and “uh”, and repeat ourselves while we think. Clean mode is an optional switch that drops those, which is what you want for notes and dictation. Leave it off when you need a word-for-word record.
So um, I think we should we should move the review to uh, Thursday.
Off: every word, as spoken.
Try it
Fluid Speech Pro is live in FluidVoice now, tuned for dictation. If you’d rather run it yourself, the weights are on Hugging Face under CC BY 4.0, free for commercial and non-commercial use. With Transformers it’s three lines:
from transformers import pipeline

asr = pipeline("automatic-speech-recognition", model="FluidVoice-Labs/fluid-speech-pro")
print(asr("audio.wav")["text"])
Clean mode, timestamps and the NeMo version are on the model card. The ONNX, MLX and GGUF versions each have their own short examples.
- NeMo + TransformersThe reference model, with the full model card.
- ONNXFor CPUs, with onnx-asr and sherpa-onnx. Full and int8.
- MLXFor Apple Silicon Macs. Full and 8-bit.
- GGUFFor parakeet.cpp, no Python needed. Full and 8-bit.
Model details
- Size
- 0.6B parameters (0.63B)
- Architecture
- FastConformer encoder and TDT decoder, with one small extra block
- Output
- Text with punctuation and capitals. Word and segment timestamps (NeMo).
- Languages
- 25, detected automatically
- Runs on
- NVIDIA GPUs (fastest), CPUs and Apple Silicon. Linux, macOS and Windows.
- License
- CC BY 4.0, free for commercial and non-commercial use
- Version
- 1.0, November 2026
Credits
Fluid Speech Pro is built on NVIDIA Parakeet TDT 0.6B v3 and Moondream Parakeet Ultra, both CC BY 4.0. Thanks to both teams for releasing their work in the open.
The FluidVoice team